

 Call Us

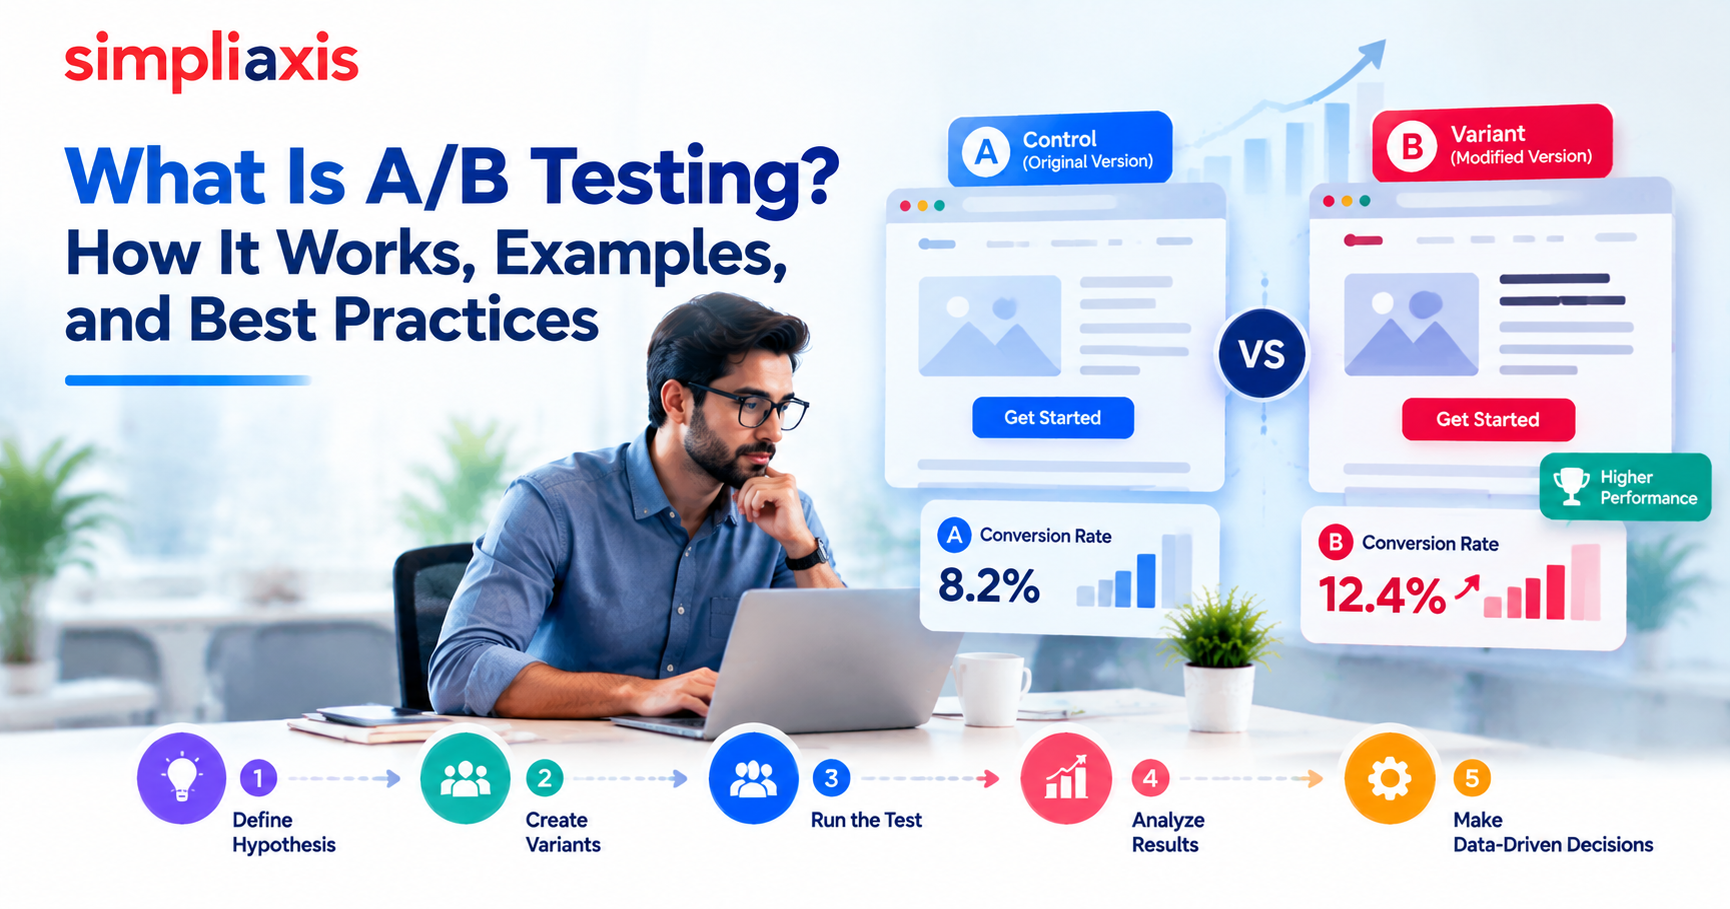
An A/B test is a controlled experiment that compares two versions of a web page, product experience, email, feature, or other digital asset to determine which performs better against a defined metric. Normally, the original version is the control, and the modified version is the variant. An e-commerce company, for instance, may test two checkout buttons to determine whether one leads to more purchases being completed. The highest conversion rate doesn’t always mean the best version. Teams also need to consider sample size, statistical significance, confidence intervals, business impact, and potential implications on other product metrics before making a decision.
Key Highlights of A/B Testing
A/B testing compares two versions of an experience, using real user behavior.
The present experience is a control. The change being trialled is a variant.
A good A/B test starts with a clear hypothesis and a pre-defined primary success metric.
Metrics like conversion rate, revenue per user, retention, engagement, and activation are frequently used in experiments.
Statistical significance tests whether the difference you see is likely to be something other than a random fluctuation.
Larger samples tend to facilitate the detection of smaller effects, and large effects can be detected with fewer observations.
Testing too many variables at the same time can make it difficult to identify what caused the result.
When you combine A/B testing with product analytics, product discovery, and a clear north star metric, it works really well.
Experiment results can be used by product owners to inform backlog priorities, product decisions, and future hypotheses.
Introduction
Every day product teams make decisions with incomplete information. 3 fields or 6 fields for a signup form? Where should testimonials go on a pricing page, above or below plans? Do you want everyone to have the new feature right away, or do you want to launch it slowly?
Absent experimentation, teams may answer these questions based on opinion, stakeholder preference, or assumptions.
Another choice is A/B testing. Test the assumption with real users and measurable outcomes. In its simplest form, A/B testing is a method to measure how users respond to a control experience versus a variant. The approach applies to marketing pages, onboarding flows, checkout experiences, emails, mobile apps, and product features.
But good experimentation is a lot more than just building two versions and waiting for a winner.
A good experiment begins with a good product question. Then, you connect that question to a testable hypothesis. You figure out what metric you'll use, how much data you need, and what statistical method you'll use to interpret the results.
This is where experimentation meets product analytics.Analytics tells you where users are struggling,product discovery techniqueshelp teams understand why the problem is happening, and A/B testing shows whether the proposed change makes the experience better.
In this guide, we’ll walk through what A/B testing is, how it works, how to run an experiment, common mistakes, real-world examples, and how product owners can benefit from experimentation in Agile and SAFe product development.
What Is A/B Testing?
A/B Testing Definition
The two versions are generally
Control (A) : Existing/Original Experience.
Variant (B): The changed experience.
Users are randomly assigned to one of the versions, and their behavior is measured against a predefined success metric.
Take, for example, an online learning platform with an 8% course enrollment rate.
The product team believes that including a brief intro from the instructor on the enrollment page will build trust and will help improve enrollment.
They produce:
Version A: Current enrollment page.
Version B: Existing page + instructor intro
If Version B produces a higher enrollment rate, the team will analyze whether the difference is statistically and practically significant.
It’s not just about which page got more clicks. We want to see whether the change provides sufficient evidence that it makes a meaningful improvement.
A/B Testing vs Split Testing vs Multivariate Testing
They are both about comparing different versions of an experience.
For example, a marketing team could send out:
Send 50% of the users to Landing Page A.
50% of the users to Landing Page B.
Then the team compares their performance.
Multivariate testing is different from A/B testing because it tests multiple variables or combinations of variables at once.
Say you want to test:
Headline A or B.
Button color A or B.
Image A versus B.
An A/B test could isolate one of these changes, one at a time.
You could do a multivariate test on combinations like:
Headline A + Image A + Button A.
Headline A + Button B + Image B
Headline B + Button A + Picture B.
Headline B + Button B + Image A.
It may give you more insight into how the elements interact with each other, but it usually means more traffic and a more complex analysis.
For low-traffic teams, simple A/B testing is often easier to design and interpret.
Why A/B Testing Matters
A/B testing matters because it gives teams a structured way to evaluate assumptions.
Instead of saying:
“We think customers will prefer the new design.”
A team can formulate:
“We believe reducing the checkout form from six fields to four will increase completed purchases because customers currently experience unnecessary friction.”
That statement can become a testable hypothesis. Harvard Business Review’sThe Surprising Power of Online Experiments shows how companies like Microsoft and Amazon use controlled experiments to settle product debates.
A/B testing can help teams:
Validate product ideas.
Improve conversion rates
Reduce friction
Improve onboarding.
Optimize pricing pages.
Test messaging.
Evaluate UI changes.
Improve activation.
Understand user behavior.
Reduce decision-making based solely on opinions.
However, not every product decision requires an experiment. Some changes may be driven by compliance, security, accessibility, technical requirements, or customer commitments.
The best experimentation programs therefore focus on high-value uncertainties, rather than testing every possible design detail.
How A/B Testing Works
Control vs. Variant
The basic A/B testing structure is straightforward.
The control is the baseline experience against which the change is measured.
The variant contains the proposed change.
Let’s say a SaaS company is currently converting free trials to paid at a rate of 20%.
The team tries out a new onboarding flow.
We might randomly split 10,000 eligible users across the two experiences. ~5,000 to the control and ~5,000 to the variant.
If the control produces 1,000 paid conversions and the variant produces 1,100, the observed conversion rates are
Control: 1,000 / 5,000 = 20%
1,100 / 5,000 = 22%
The relative lift observed is 10%.
That doesn’t mean, however, that the new onboarding flow should be rolled out automatically.
The team still needs to determine whether the difference is sufficiently supported by the data and whether the improvement matters commercially.
Hypotheses and Success Metrics
Every good A/B test begins with a hypothesis.
A useful structure is
Because [observation], we believe [change] will cause [outcome] for [audience]. We will measure this using [metric].
For example:
We think that a three-step product walkthrough will lead to better activation for first-time users, as new users have trouble understanding the value of our platform. The change will be measured by the percentage of users who perform their first key action within 7 days.
This is stronger than simply saying, “Let's test a product walkthrough.”
The hypothesis connects:
Problem → Change → Expected outcome → Measurement
The primary metric should be selected before the test begins and should ladder up to the team’sOKRs and KPIs. Depending on the experiment, that might be
Conversion rate.
Activation rate.
Revenue per visitor.
Average order value.
Trial-to-paid conversion.
Retention.
Feature adoption.
Completion rate.
Time to complete a task.
Teams should also consider guardrail metrics.
For example, a new checkout design may lead to more purchases but also more refund requests or customer support contacts.
Looking at only one metric can therefore produce an incomplete picture.
Statistical Significance and Confidence
Statistical significance comes fromhypothesis testing, and helps teams evaluate whether an observed difference is unusual enough to suggest the control and variant don’t perform identically.
It is important to distinguish statistical significance from business significance.
If an experiment takes a conversion from 10.00% to 10.05%.
That small difference could be statistically significant if the sample is large enough.
But the improvements may not be worth the engineering effort it takes to implement them.
If you see a 10% improvement from a very small sample, in contrast, it may look promising but not give enough evidence to roll out.
Statistical methods differ. Fixed-horizon methods typically require that the sample size and analysis plan be fixed in advance, while sequential and Bayesian approaches can permit a variety of ways to monitor and interpret experiments.
Confidence intervals are also useful because they show the range of plausible effect sizes rather than reducing the result to a simple “winner” or “loser.”For a deeper treatment, see Kohavi, Tang and Xu’sTrustworthy Online Controlled Experiments.
How to Run an A/B Test Step by Step
Step 1: Form a Clear Hypothesis
Start with the problem rather than the feature.
Weak hypothesis:
“Let's test a green button.”
Stronger hypothesis:
“Because users may not recognize the current primary action, making the CTA more explicit will increase completed registrations.”
The second version explains why the change is expected to work.
This is important because even a failed experiment can produce useful learning when the hypothesis is clear.
Step 2: Choose One Variable to Test
When possible, isolate the major variable you want to understand.
For example, if you want to know whether CTA wording affects registration, don't simultaneously change:
Button text.
Button color.
Page layout.
Headline.
Form fields.
If registrations improve, you won't know which change caused the result.
Testing one primary variable at a time makes the causal story easier to understand.
There are times when testing a full experience makes sense, but teams should understand at that point that they are testing the combined experience and not isolating a variable.
Step 3: Decide Sample Size and Duration
Sample size is one of the most important parts of experiment design.
It depends on factors such as
Baseline conversion rate.
Minimum detectable effect (MDE).
Desired statistical power.
Significance threshold.
Number of variants.
Metric variability.
Traffic volume.
Smaller effects generally require more data to detect reliably. Sample-size planning should match the statistical test and assumptions being used.
There’s no hard and fast rule of “every A/B test takes exactly two weeks.”
Instead, calculate the right sample size and duration for your experiment design and expected traffic.
Normal business variation should also be included in the test, where applicable. For example an e-commerce site may behave differently on weekdays and weekends.
Step 4: Execute the Test
Once the experiment is launched, users need to be assigned according to the experiment design.
Just because the first results look good, don't change your hypothesis halfway through.
A common problem is peeking: repeatedly checking the results and stopping when the preferred version appears to be winning.
The earlier you look in a fixed-horizon test and stop, the greater the chance you will get false positives. Sequential testing methods are specifically designed to treat continuous tracking differently, so teams should understand what statistical approach their experimentation platform uses.Evan Miller’s classic explainer,How Not To Run an A/B Test, shows how repeated peeking inflates false positives.
During the test, watch out for technical problems such as:
Improper traffic allocation.
Tracking failure.
Broken varieties.
Severe performance problems.
Unexpected user groups
Conversion events are missing.
Step 5: Interpret Results and Decide
Analyze when the experiment reaches its predefined decision criteria:
Primary Measure.
Size of effects.
Statistical evidence.
Confidence interval.
Guardrail metrics.
Business impact.
Implementation cost.
Suppose a new pricing page produces:
12% higher trial starts.
No statistically convincing change in paid conversion.
5% higher customer-support contacts.
The team should not automatically conclude that the test was a success.
The correct decision might be to investigate why trial starts increased without a corresponding improvement in downstream outcomes.
Experimentation is ultimately about learning, not collecting winning screenshots.
A/B Testing Examples
Example 1: E-Commerce Checkout
An online retailer learns via product analytics that a large percentage of users abandon the checkout process. The team believes that taking away unnecessary form fields will increase completion.
Control: 8 checkout fields.
Option: Five checkout fields.
Primary metric: Completed purchases
Guardrail metrics: Refunds, payment failures, customer support contacts.
If the variant increases purchases without damaging the guardrail metrics, the team has evidence in favor of the change.
Example 2: SaaS Onboarding
A project-management platform finds that only 35% of new users actually create their first project during onboarding.
The product team thinks that users need more guidance.
Control: Business as usual with onboarding.
Guided: 3-step setup (Variant)
Key metric: First project created.
Secondary metrics: 7-day activation and retention.
This experiment can help you understand if the new onboarding actually helps users achieve meaningful product value.
Example 3: Landing Page Messaging
A B2B software firm wants to test what resonates better with customers – customer outcomes or feature descriptions.
Control tagline: Powerful Workflow Automation Software.
Variation headline: “Save Hours Every Week by Automating Repetitive Tasks.”
The main metric is the number of qualified demo requests.
This is a pretty big difference. If your goal is to generate qualified leads, only tracking button clicks may optimize for the wrong behavior.
Example 4: Mobile App Feature Adoption
A mobile banking app launches a new budgeting feature.
The product owner wants to know whether users discover it naturally.
Control: Existing home screen.
Variant: Home screen with a prominent budgeting card.
Primary metric: Budgeting-feature activation.
Guardrail: Overall session abandonment.
The result could inform whether the feature needs better visibility, a different onboarding experience, or additional product discovery work.
Example 5: Email Subject Lines
A subscription company tests two subject lines.
Control: “Your weekly product update”
Variant: “Three ways to get more from your subscription”
The primary metric could be email open rate, but the team should consider downstream behavior too.
A higher open rate is useful only if it ultimately contributes to the intended customer or business outcome.
This is where broader product metrics become valuable.
Common A/B Testing Mistakes
A/B testing can create misleading results when experiments are poorly designed.
Common problems include:
Testing without a clear hypothesis.
Choosing the metric after seeing the results.
Using too little traffic.
Running too many variants.
Changing multiple variables without a clear reason.
Stopping as soon as a version appears to win.
Ignoring seasonality.
Ignoring technical implementation issues.
Focusing only on statistical significance.
Testing low-impact changes.
Treating correlation as causation.
Ignoring downstream effects.
Running experiments on overlapping audiences without accounting for interaction effects.
A statistically significant result is not automatically a valuable product decision.
Peeking, Small Samples and Testing Too Much at Once
Three mistakes deserve particular attention.
Peeking: A team repeatedly checks results and stops the experiment when the preferred variation becomes statistically significant. This can bias error rates with testing on a fixed horizon.
Small samples If the data are too scarce to see the effect you are looking for, the test may be inconclusive or unstable. The sample size should be determined by the baseline metric and the minimum detectable effect.
Too many variables: Running too many variants, metrics, and audience segments simultaneously, makes analysis harder, and may increase the chance of a statistically significant finding happening by chance if the statistical approach does not take multiple comparisons into account.
The answer is disciplined experimentation: before the experiment begins, define the question, metric, audience, sample requirements, statistical method and decision criteria.
A/B Testing Tools
The best A/B testing tool for you will depend on your team’s technical environment, traffic levels, experimentation maturity, and analytics stack.
Common categories include:
Experimentation Platforms
Dedicated platforms can allow teams to create variants, assign users, monitor experiments and analyze results.
Examples include Optimizely and other experimentation platforms for web or product experimentation.
Product Analytics Tools
Product analytics tools allow teams to understand user journeys before and after an experiment.
For example, teams might examine:
Funnels.
Cohorts.
Retention.
Feature adoption.
User paths.
Conversion events.
For a broader view of how teams analyze behavioral data, see thesedata analysis methods.
Feature Flagging Platforms
Feature flags allow teams to expose functionality to selected users or segments and gradually ramp up exposure.
This is useful when experimentation is tightly coupled with delivery, and works alongside release strategies such asblue-green deployment.
Data and Statistical Tools
Organizations with mature data teams may use SQL, Python, R, notebooks, or internal experimentation systems to analyze results. These are skills covered inData Science with Python training.
The important point is that the tool should support sound experimental design. A sophisticated dashboard cannot compensate for a poorly designed experiment.
A/B Testing in Agile and SAFe Product Work
A/B testing fits naturally intoAgile product developmentbecause Agile teams are designed to deliver increments, gather feedback, and adapt.
Rather than simply looking at whether a feature shipped, teams can ask whether it changed the intended customer or business outcome.
This creates a useful loop:
Hypothesis → Build → Experiment → Measure → Learn → Prioritize
For Product Owners, whoseroles and responsibilitiesinclude maximizing product value, the results can feed directly into backlog decisions
Hypothesis-Driven Development and the Product Increment
The development is hypothesis-driven: you begin with a hypothesis about a customer problem or behavior, and the product change is your experiment.
For instance:
“We believe new users churn out during onboarding because they don’t know what the first thing they should do is.
The team could make a small change to onboarding as part of a product increment and test whether it improves activation.
This ties together product discovery with delivery.
Teams can identify important uncertainties and find ways to test them sooner, rather than spending months building a large solution based on assumptions.
Not all features have to be released experimentally. Security, compliance, infrastructure and other changes may require different validation approaches.
However, wherever user behavior can be measured, experimentation can help reduce uncertainty.
You can learn more about this approach through theProduct discoveryresource.
Turning Test Results Into Backlog Decisions
A/B test results become most valuable when they influence what the team does next.
Imagine a Product Owner tests a simplified signup process and sees a meaningful improvement in activation.
The result could lead to:
Making the change permanent.
Expanding it to additional user segments.
Testing a related onboarding hypothesis.
Investigating downstream retention.
- Updating the product roadmap usingAgile prioritization techniques
- Reprioritizing the product backlog
Alternatively, if the test fails, the team might:
Reject the proposed change.
Investigate why the hypothesis failed.
Conduct additional product discovery.
Run a qualitative research study.
Test a different solution.
Revisit the underlying problem.
Here, experimentation is directly tied to product metrics and product strategy.
Teams should also understand how experiments feed into their north star metric.
A north star metric is a critical indicator of customer value that provides a common direction for product teams. It shouldn’t replace experiment-specific metrics, but it can help teams understand if their local improvements matter to broader product outcomes.
See North Star metric for more information.
Experimentation can also help guide backlog prioritization and product decisions across Agile teams for practitioners in SAFe environments. Learn more throughSAFe POPM roles and responsibilities.
Product Owners looking to develop their SAFe product skills can also exploreSAFe POPM Certification Training.
Conclusion
A/B testing gives product teams a practical way to replace assumptions with evidence. Teams can compare a control with a variant to see whether a given change has an effect on a predefined outcome.
But successful experimentation is more than just finding a statistical winner. Teams need a clear hypothesis, the right metric, sufficient sample size, right statistical approach and a decision framework that considers both statistical and business significance.
A strong experimentation process can cover the entire product lifecycle: product discovery uncovers opportunities, product analytics helps to understand user behavior, A/B testing tests hypotheses and product metrics allow teams to measure the impact of their work.
This means that Product Owners get a powerful feedback loop. Instead of asking if a feature was delivered, they can ask if it solved the problem it was supposed to solve and if it delivered meaningful product outcomes.
When used consistently and mindfully, A/B testing becomes much more than just a method of conversion optimization. It enables product teams to learn faster, deal with uncertainty and make better product decisions.


 Lowest-Price Challenge







 Personalized Path


.webp)


 USA
 Canada
 India
 UK
 Australia
 Singapore


